Repository navigation
[BUG] Composite charts should not mix plugins together #351
Description

When we have multiple different operating systems, like linux and freebsd, the context of charts remain the same, but the dimensions are different for each operating system.
This is not a problem for single node dashboards, because every single node dashboard only one version of them.
However, in composite charts, this becomes messy.
Examples:
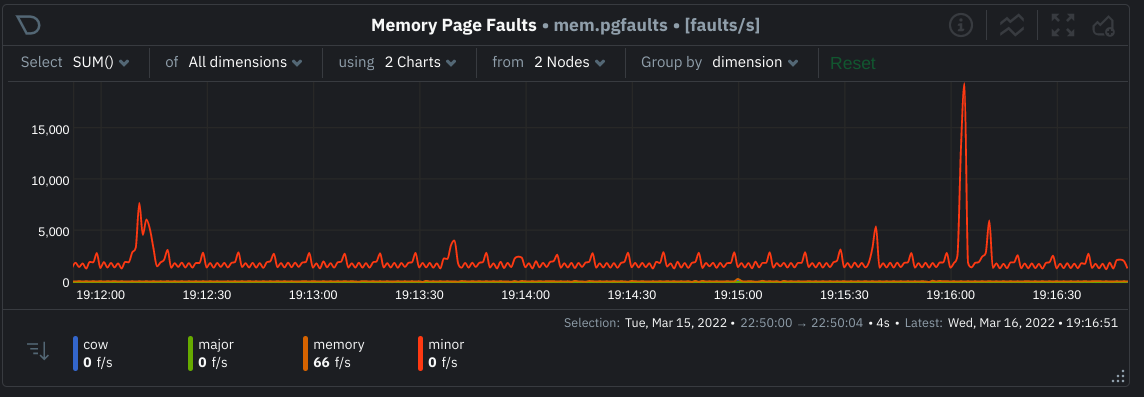
Page faults chart from both linux and freebsd:
Dimensions cow and memory come from freebsd. Dimensions minor and major come from linux.
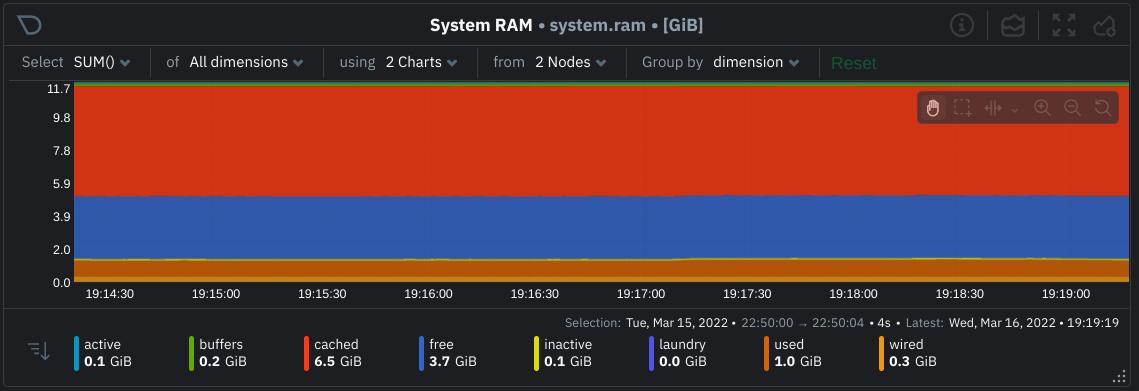
Memory chart from both linux and freebsd:
FreeBSD has free, active, inactive, wired, laundry and buffers
Linux has free, used, cached and buffers
Discussion
This issue is also related to #347
So, when we have a context that has been generated by 2 different plugins, the charts should not be merged in composite dashboards.
The fact that charts on composite dashboards have different aggregations (some charts come from 1 node, others come from 2 nodes, etc) makes the composite dashboard more difficult to understand. Just paying attention to the nodes or charts counter, is not the right way to present this information.
Something is missing here to give clarity to the dashboard.
This ticket is about discussing the right solution. No action to be taken for the moment.
Activity
cakrit commentedon Jun 1, 2022
This is another that is probably for the agent, not the cloud, but we'll discuss first.
hugovalente-pm commentedon Jun 9, 2022
without the work on being completed the only quick and dirty option I see #354 is to tweek with families to have subsections for each
where we could have a have
what do you think @ktsaou @amalkov @papazach @novykh @stelfrag @ilyam8 ?
hugovalente-pm commentedon Jun 16, 2022
just ping to see if you have any feedback on this @ktsaou @amalkov @papazach @novykh @stelfrag @ilyam8 ?
hugovalente-pm commentedon Jul 13, 2022
@ktsaou @amalkov @papazach @stelfrag @ilyam8, guys what do you think about this one? shall we icebox it until the work on #354 is completed?
novykh commentedon Sep 15, 2022
2-3 months later, I agree with the family grouping.
hugovalente-pm commentedon Sep 19, 2022
for this one we can see what we will be doing on this one as well #550, I know that one was more describing PostgreSQL but we will need to have a rule(s) that could also help on this one
amalkov commentedon Sep 20, 2022
@hugovalente-pm agree with you, this can be resolved together with #550
hugovalente-pm commentedon Sep 30, 2022
I think this bug can be closed, this was raised for discussion and we identified that we have a short-term solution described here with #550 and the long-term solution is the #354