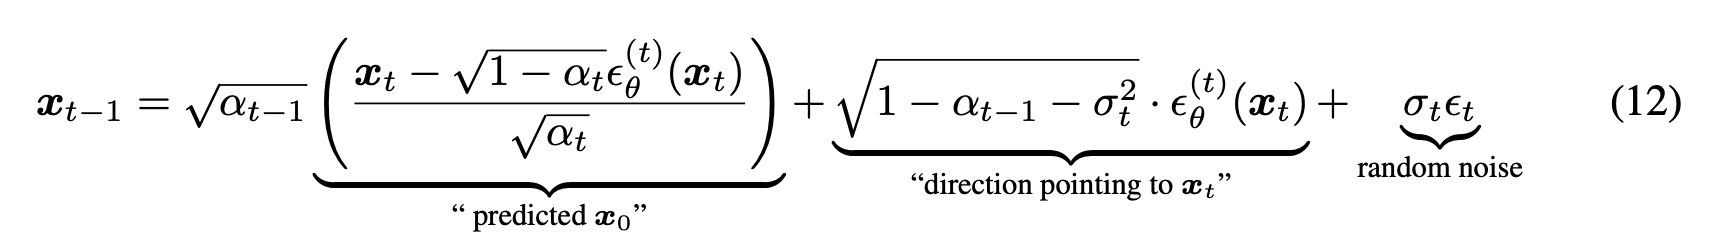Repository navigation
clip-guided stable diffusion correctness #596

Description

Describe the bug
the clip-guided pipeline uses these text-embeddings:
diffusers/examples/community/clip_guided_stable_diffusion.py
Lines 285 to 288 in 2345481
defined earlier as:
diffusers/examples/community/clip_guided_stable_diffusion.py
Lines 234 to 237 in 2345481
which I read as using the unconditioned (i.e. null prompt) embeddings.
Is that the way it's supposed to work? That doesn't feel like how it's supposed to work. Like, if the normal classifier-free guidance function is turned off, it would be using the embeddings from the text prompt, not the nulls.
But this pipeline was added without any tests or samples or other reference material, so I really don't know.
Reproduction
No response
Logs
No response
System Info
👀
Activity
patrickvonplaten commentedon Sep 22, 2022
cc @patil-suraj might be good to take a look soon since we just released it :-)
keturn commentedon Sep 23, 2022
Someone posted another concern on discord:
patil-suraj commentedon Sep 28, 2022
That's a great catch @keturn ! Sorry to come back to this only now, will send a fix right away.
patil-suraj commentedon Sep 28, 2022
Also updated the colab notebook https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/CLIP_Guided_Stable_diffusion_with_diffusers.ipynb#scrollTo=-bzXx-2EhlQY
ajundo commentedon Sep 29, 2022
Afaik, this is correct because the conditional diffusion is conditional on predicted x_t rather than predicted x_0。
zzhang2816 commentedon Apr 11, 2023
I think the correct format is "sample = pred_original_sample * (fac) + noise_pred * (1 - fac)"